David Castillo
PHP2Shell in a Box: Exploiting CVE-2026-109618 and CVE-2026-109619 on a Local PHP 8.5.11 Lab
How I built a deliberately vulnerable PHP 8.5.11 + PostgreSQL shop in Docker and wrote two self-contained Python exploits for the PHP2Shell ...
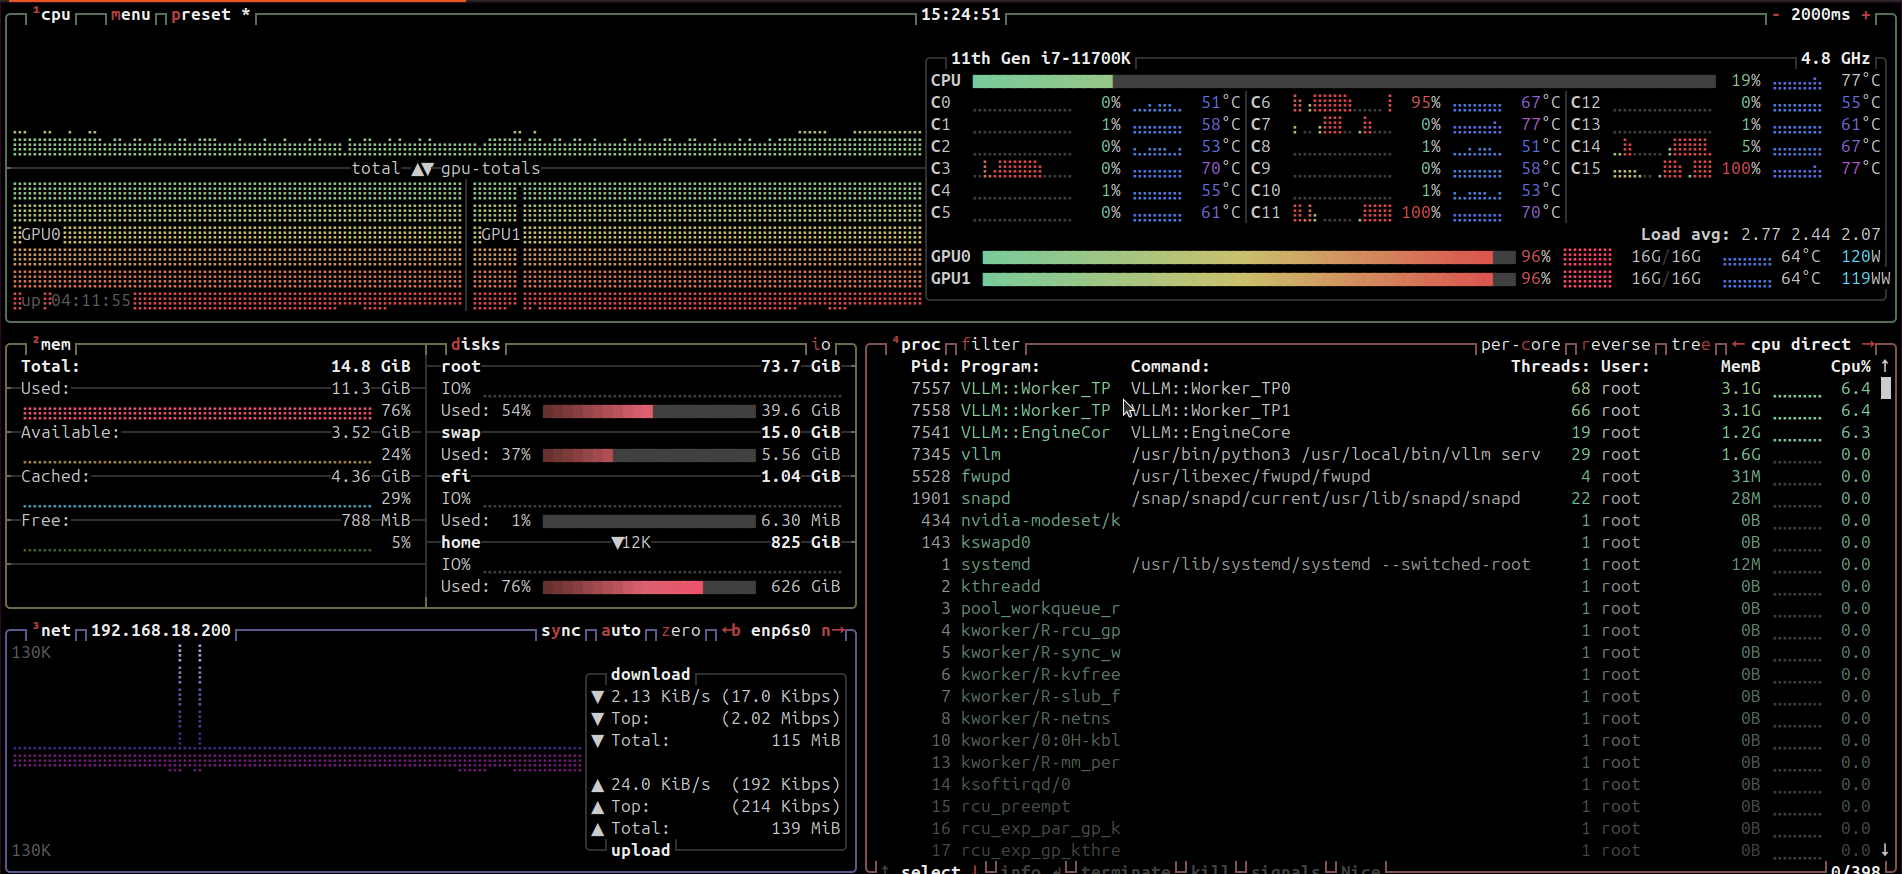
Running vLLM on Consumer Hardware: The VRAM Math, Memory Management, and Why It Beats llama.cpp
How I run vLLM on the same consumer rig as my llama.cpp setup: the real VRAM budget (weights, MTP, KV cache, PyTorch overhead), why the repo...
Running Local LLMs on Consumer Hardware: A Practical Guide
How I deployed and optimized local LLMs on a 5-year-old consumer PC using llama.cpp, from hardware bottlenecks to advanced inference techniq...